01
Performance Optimisation
Find and remove frontend, backend and database bottlenecks across critical journeys.
After launch, we improve performance, ship continuously, control cloud costs and provide the engineering support needed to scale with confidence.
 See how we build
Find and remove frontend, backend and database bottlenecks across critical journeys.
Run a dependable roadmap of product improvements and new releases.
Improve data models, queries, indexes, caching and capacity for growth.
Establish observability, ownership and response processes for critical systems.
Upgrade fragile systems without disrupting the workflows they support.
Improve throughput, resilience and observability across services and integrations.
Reduce infrastructure waste while protecting performance and reliability.
Add a focused product team that owns outcomes, quality and continuous delivery.
Monitoring, cloud and delivery tools for products that cannot stand still.
Monitoring, cloud and delivery tools for products that cannot stand still.
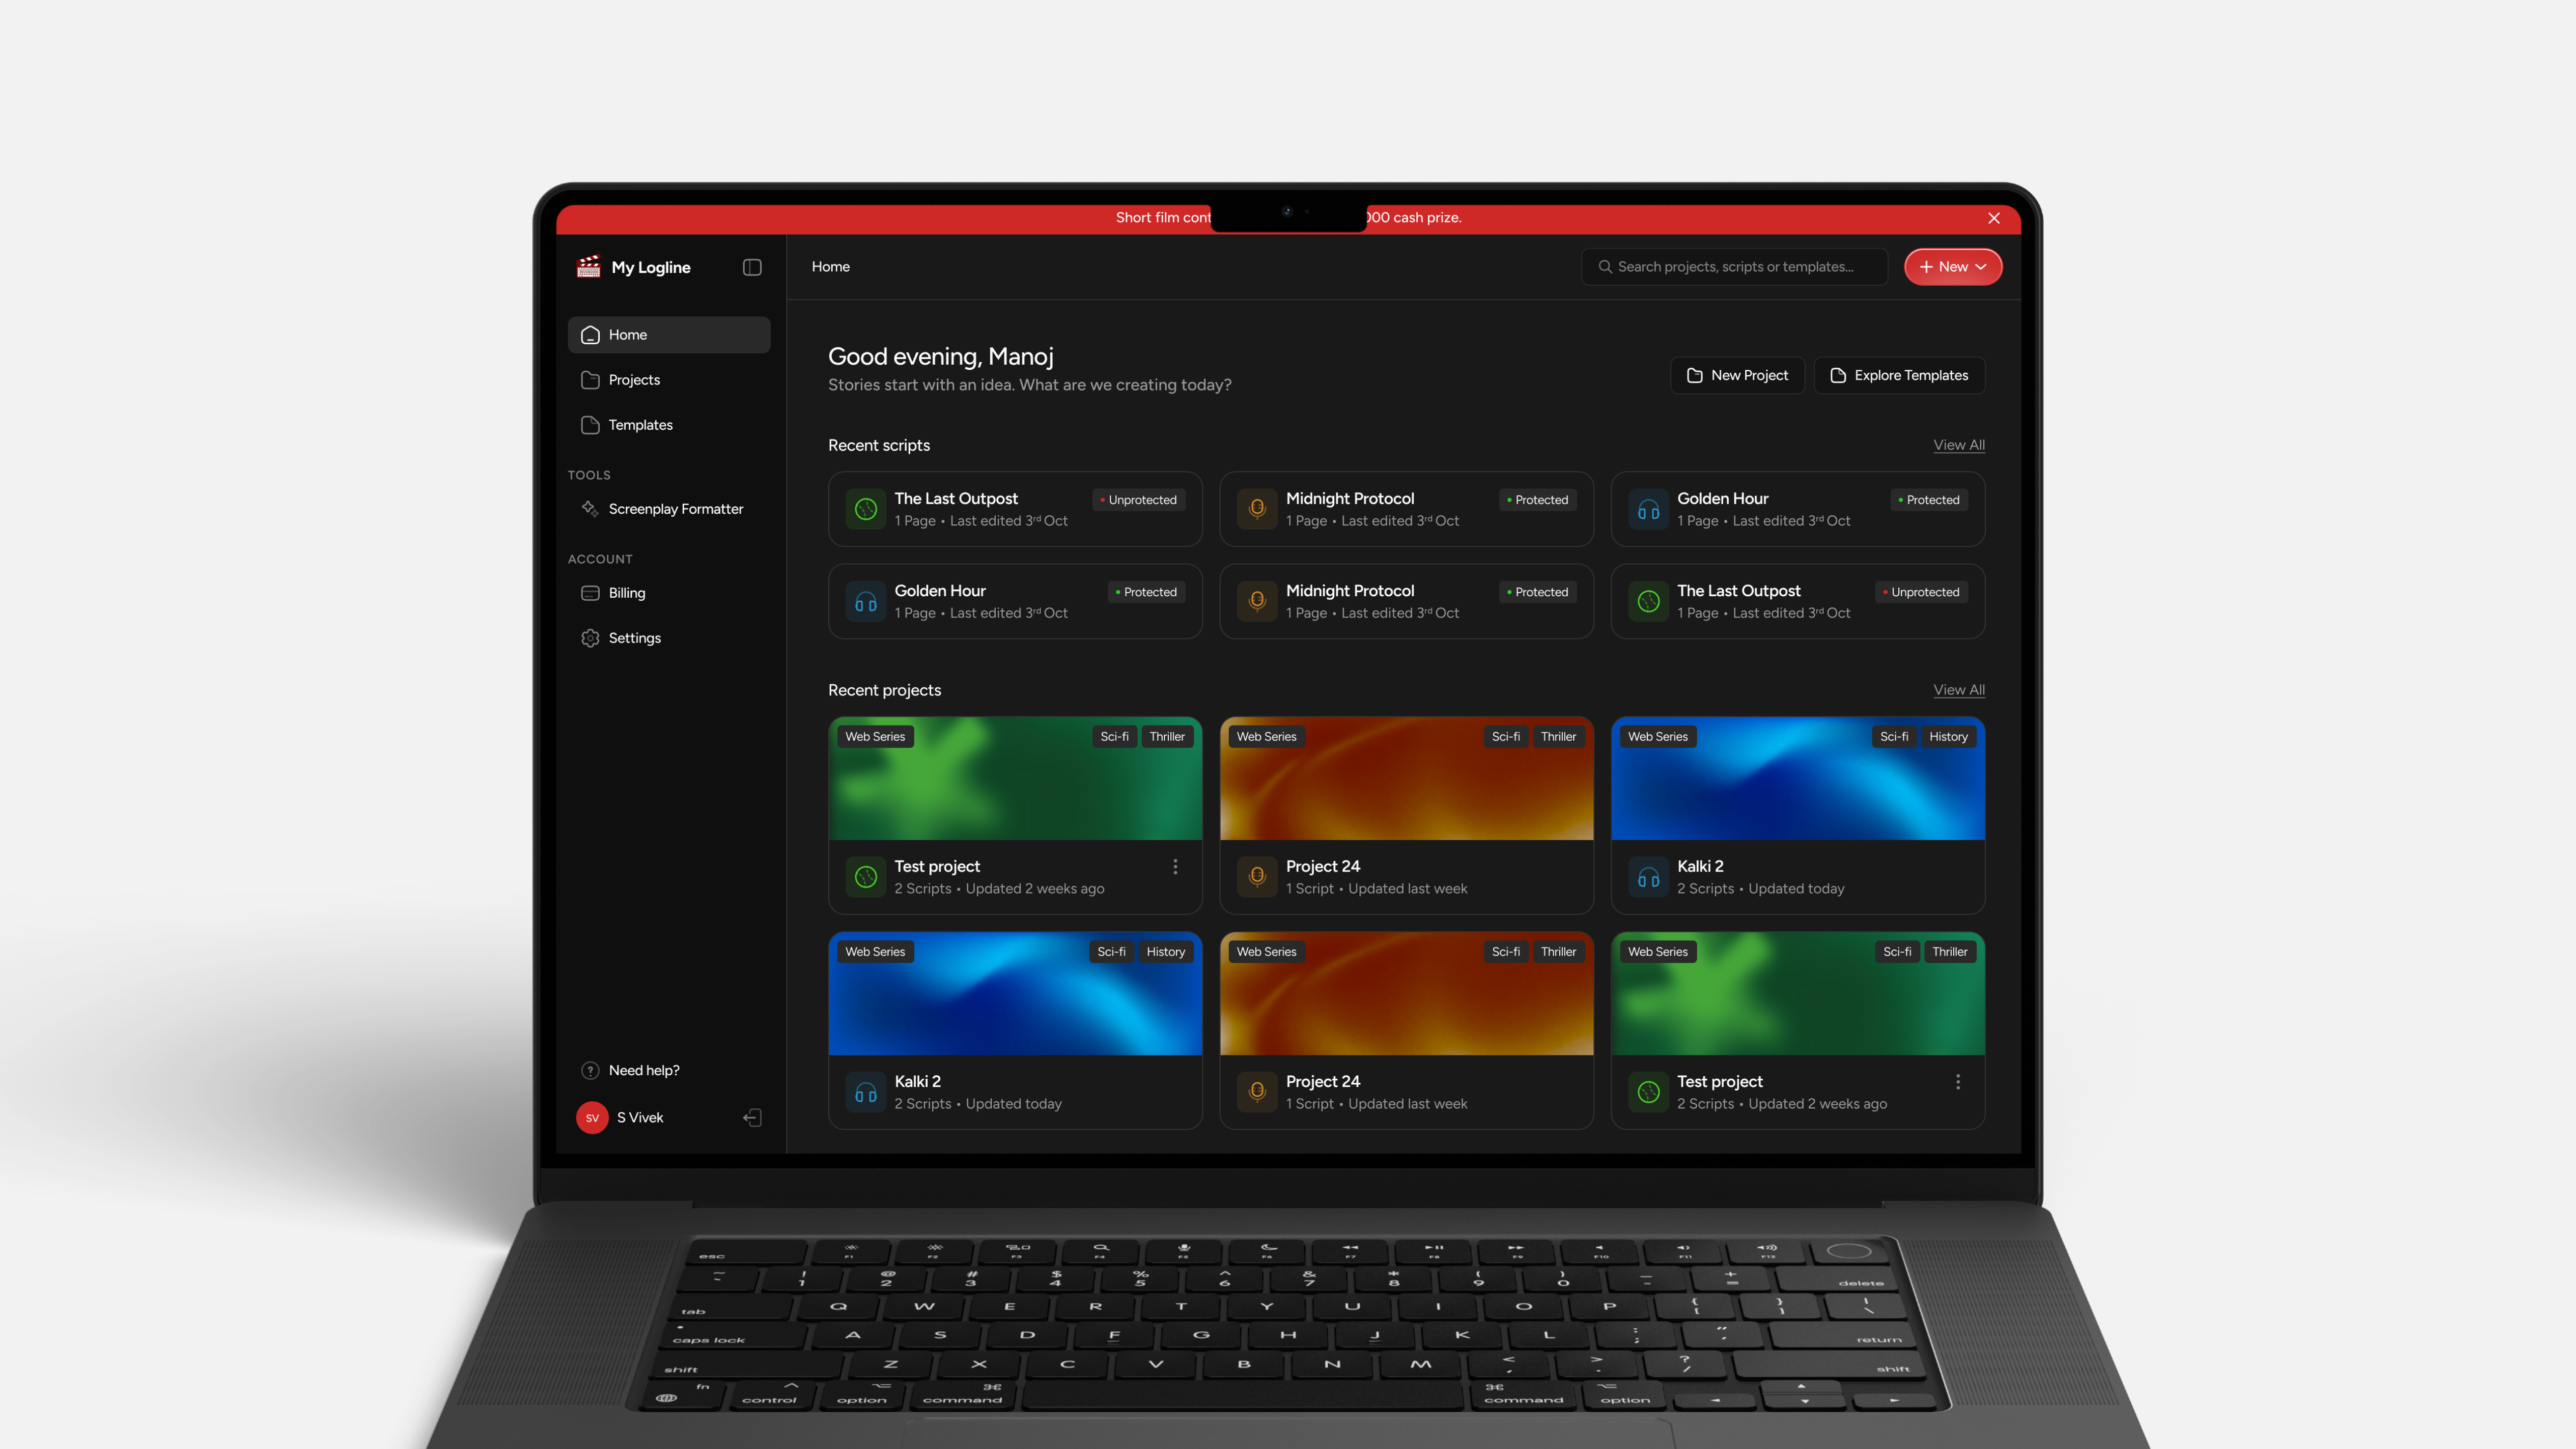
 MYLOGLINE
A subscription SaaS built to keep evolving after a 30-day launch, with AI usage, collaboration, billing and product feedback creating a foundation for continued growth.
 View more works
“I was incredibly impressed with their high-quality outputs and the wonderful design outcomes they delivered. Beyond the great work, their team is highly adaptable and always able to seamlessly switch priorities on the fly whenever our needs shifted.”
Send us some more context and we’ll tell you if we’re a fit.
Or email us → office@quicktapservices.com

Yes. We begin with a structured codebase and infrastructure review, document the current state and create a safe transition plan.
Yes. Engagements can cover planned improvements, monitoring, incidents, security updates, performance and technical leadership.

We establish severity levels, ownership, communication, diagnostics and post-incident learning so the team can restore service and reduce repeat failures.

Often, yes. We profile the actual bottlenecks and prioritise focused changes to queries, caching, rendering, APIs and infrastructure before considering major rewrites.

Yes. We analyse utilisation, architecture and workload patterns, then address idle resources, oversized services, storage, data transfer and inefficient application behaviour.

We combine code and infrastructure review with stakeholder interviews, production evidence and incremental documentation, then address the highest-risk gaps first.

Yes. We balance reliability work with a clear feature roadmap and use the same delivery and quality controls for both.

We support early products preparing for growth as well as established systems that need stronger performance, delivery and operational ownership.

Tell us a little about you & the project. Our team will read it and reply within 24 hours.

Drop your details and we’ll reach out to you.